AI software factories: what they are and how to build one that ships
- What a software factory is, and what it isn't
- Do you need a factory, or just better engineering?
- What a factory does all day
- The factory loop, step by step
- A 30-day plan
- 5 types of factory, and which one to build
- Standardize everything
- Review screenshots and videos, not diffs
- Local or remote
- Tools to start with
- Measure it, or it's theater
- What a factory won't do for you
What a software factory is, and what it isn't
- Each agent owns one area and has its own Slack account. One helps support, one owns the Bundles app, one owns their AI product. People tag them in threads like a teammate.
- They don't wait for tickets. The Bundles agent reads Sentry, logs, support chats, uninstall reasons and funnels, then opens its own issues and PRs.
- Every PR gets the same review, human PRs too: Claude and Codex hunt bugs in the diff, a security scan runs on risky changes, and an "approach pass" asks if the code should exist at all.
- A human merges. Agents never merge, approve or deploy to production, and their database access is read-only.
- Rules compound. When a developer says "don't do X" once, it becomes a rule in
AGENTS.mdor a skill, and all 9 agents follow it.
- Giving every engineer Claude Code or Cursor. Useful, but nothing takes a ticket from intake to merge on its own.
- A folder of skills and MCP servers that everyone installs.
- One agent with access to your repo. That's the build loop without the factory around it.
- A swarm of agents in one long chat. Each agent rereads everything, and you pay for it every time.
- A few cron jobs around cloud agents that nobody measures.
Do you need a factory, or just better engineering?
AGENTS.md come after. Human review is the smallest layer at the bottom. A factory built on a messy repo is a fast way to make more mess.We set up software factories on your stack: CI gates, review agents, QA on previews, Sentry-to-PR fixes, changelogs and SEO, with your developers and on your real tickets.
 Build my factory
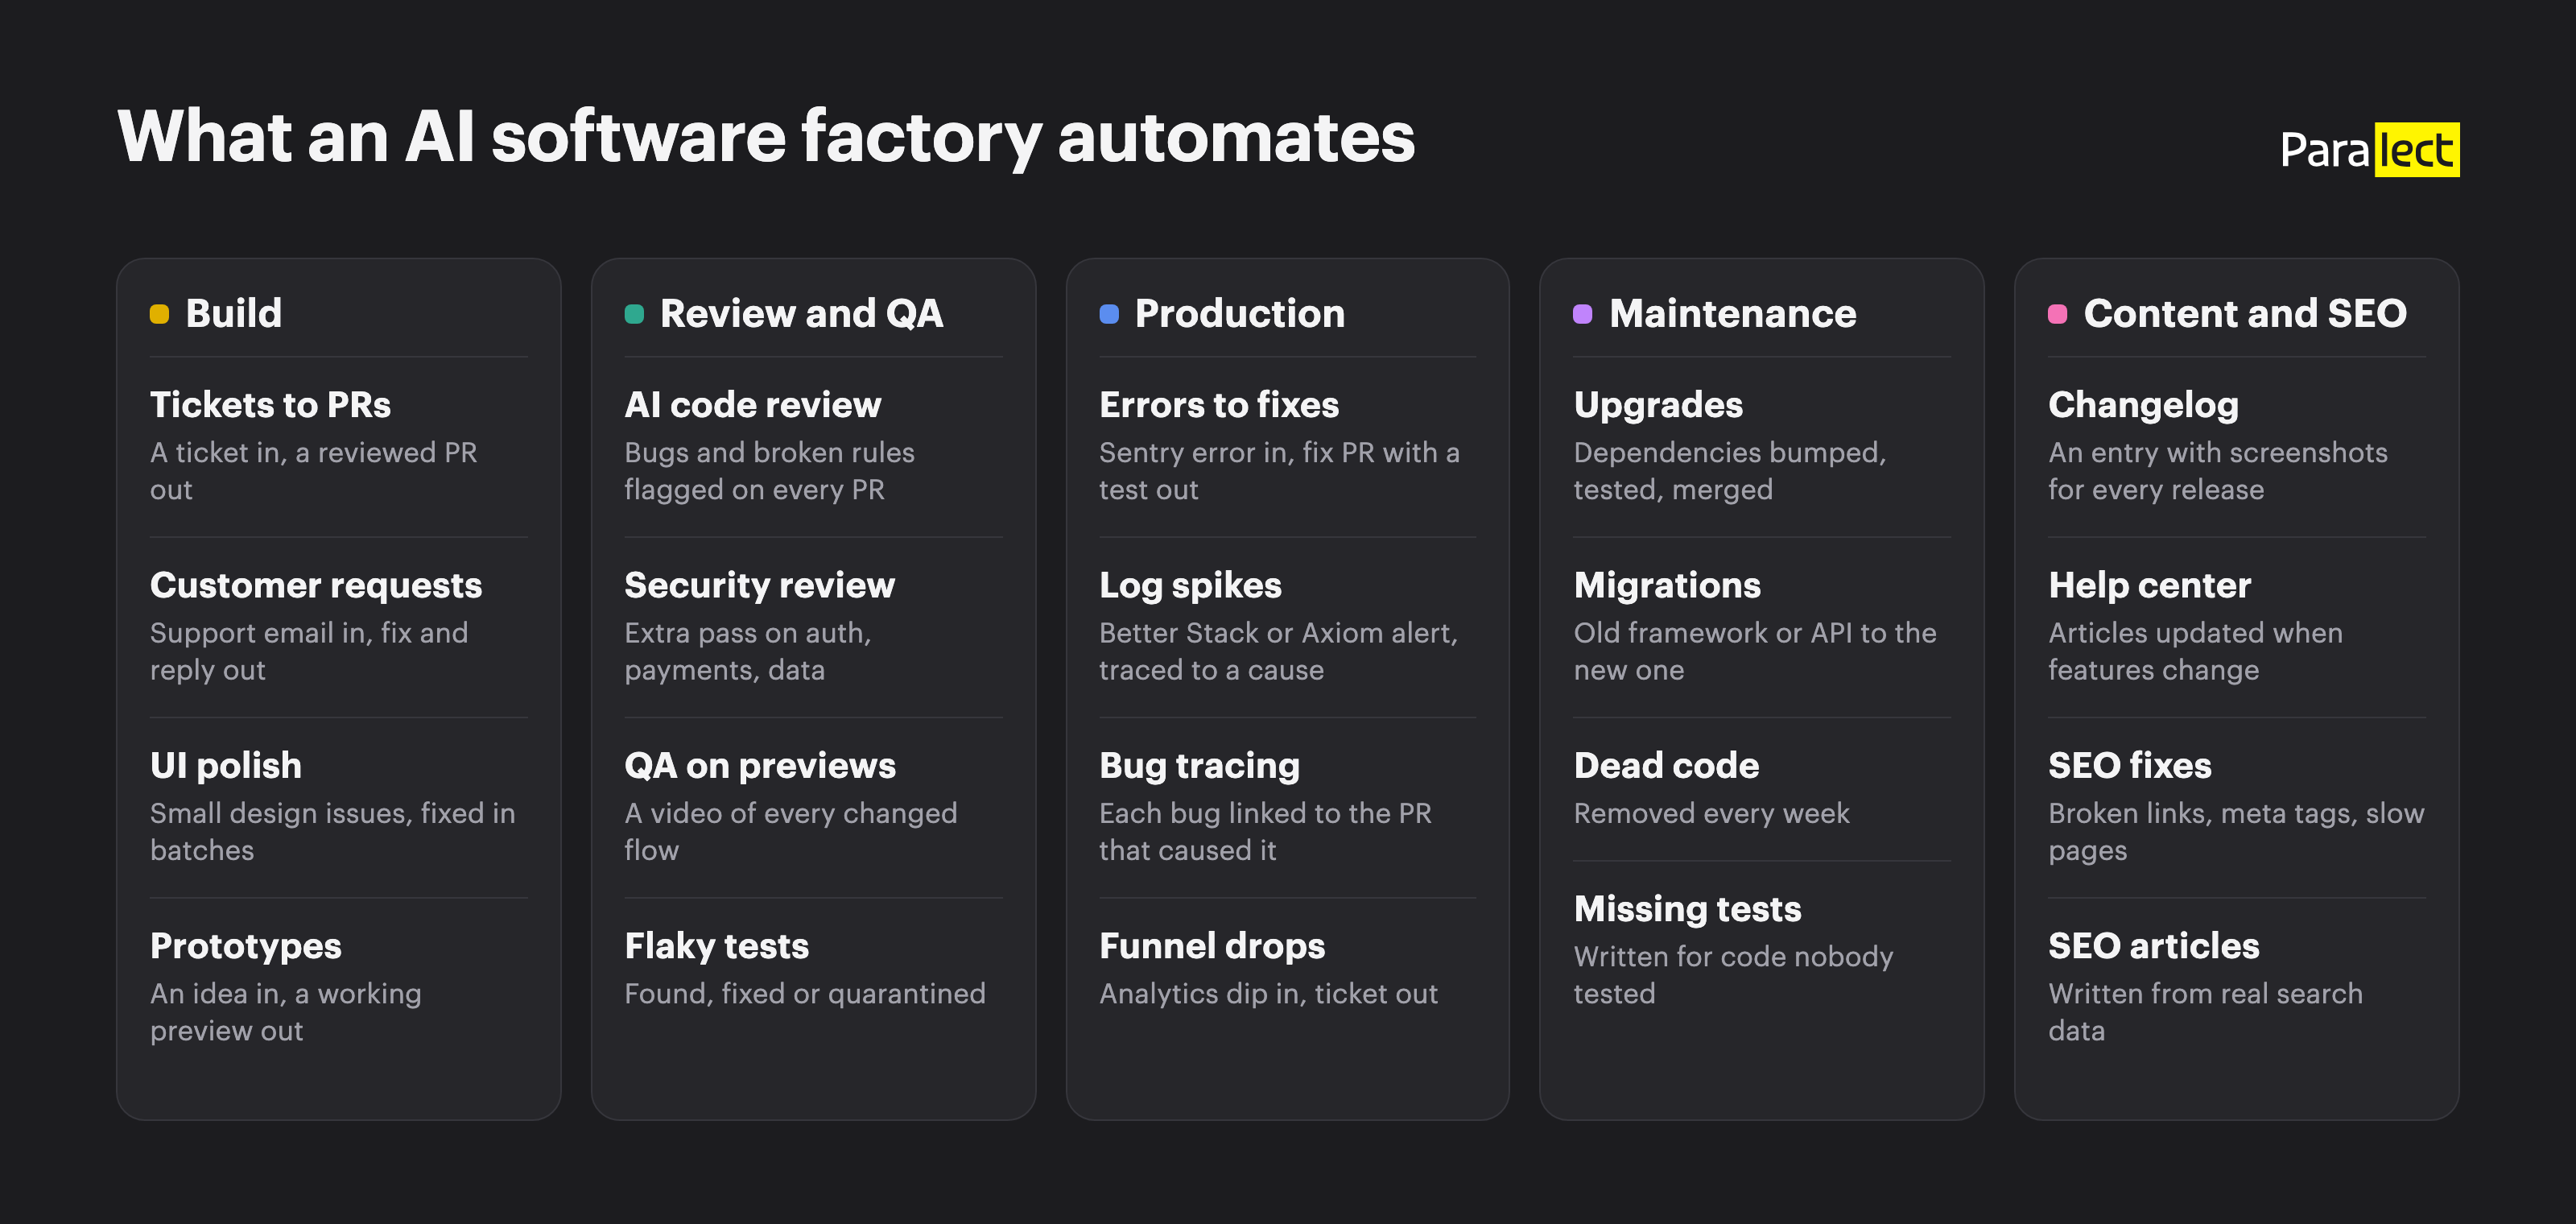
What a factory does all day
| Job | What starts it | What the agent does | How you check it |
|---|---|---|---|
| PR review | Every PR | Comments on bugs, security holes, broken conventions | You accept or ignore the comments |
| QA | Every preview deploy | Clicks through the changed flows with Playwright, records a video | You watch the video |
| Errors and logs | Groups duplicates, finds the cause, opens a fix PR with a test that reproduces the bug | The error stops coming | |
| Changelog and help center | A merged PR or a release | Writes the changelog entry with screenshots, updates the help articles the change touched | Read it, 2 minutes |
| SEO | A weekly audit, Search Console data | Fixes broken links, meta tags, slow pages, writes articles from real search data | The audit passes, pages get indexed |
| Customer requests | A support email, an Intercom chat, a Slack message | Turns it into a ticket with steps to reproduce, fixes small ones, drafts the reply | The customer confirms |
| New features | A ticket moved to "Ready" in Linear or GitHub | Writes a plan, builds it, opens a PR | You review the result on staging |
The factory loop, step by step
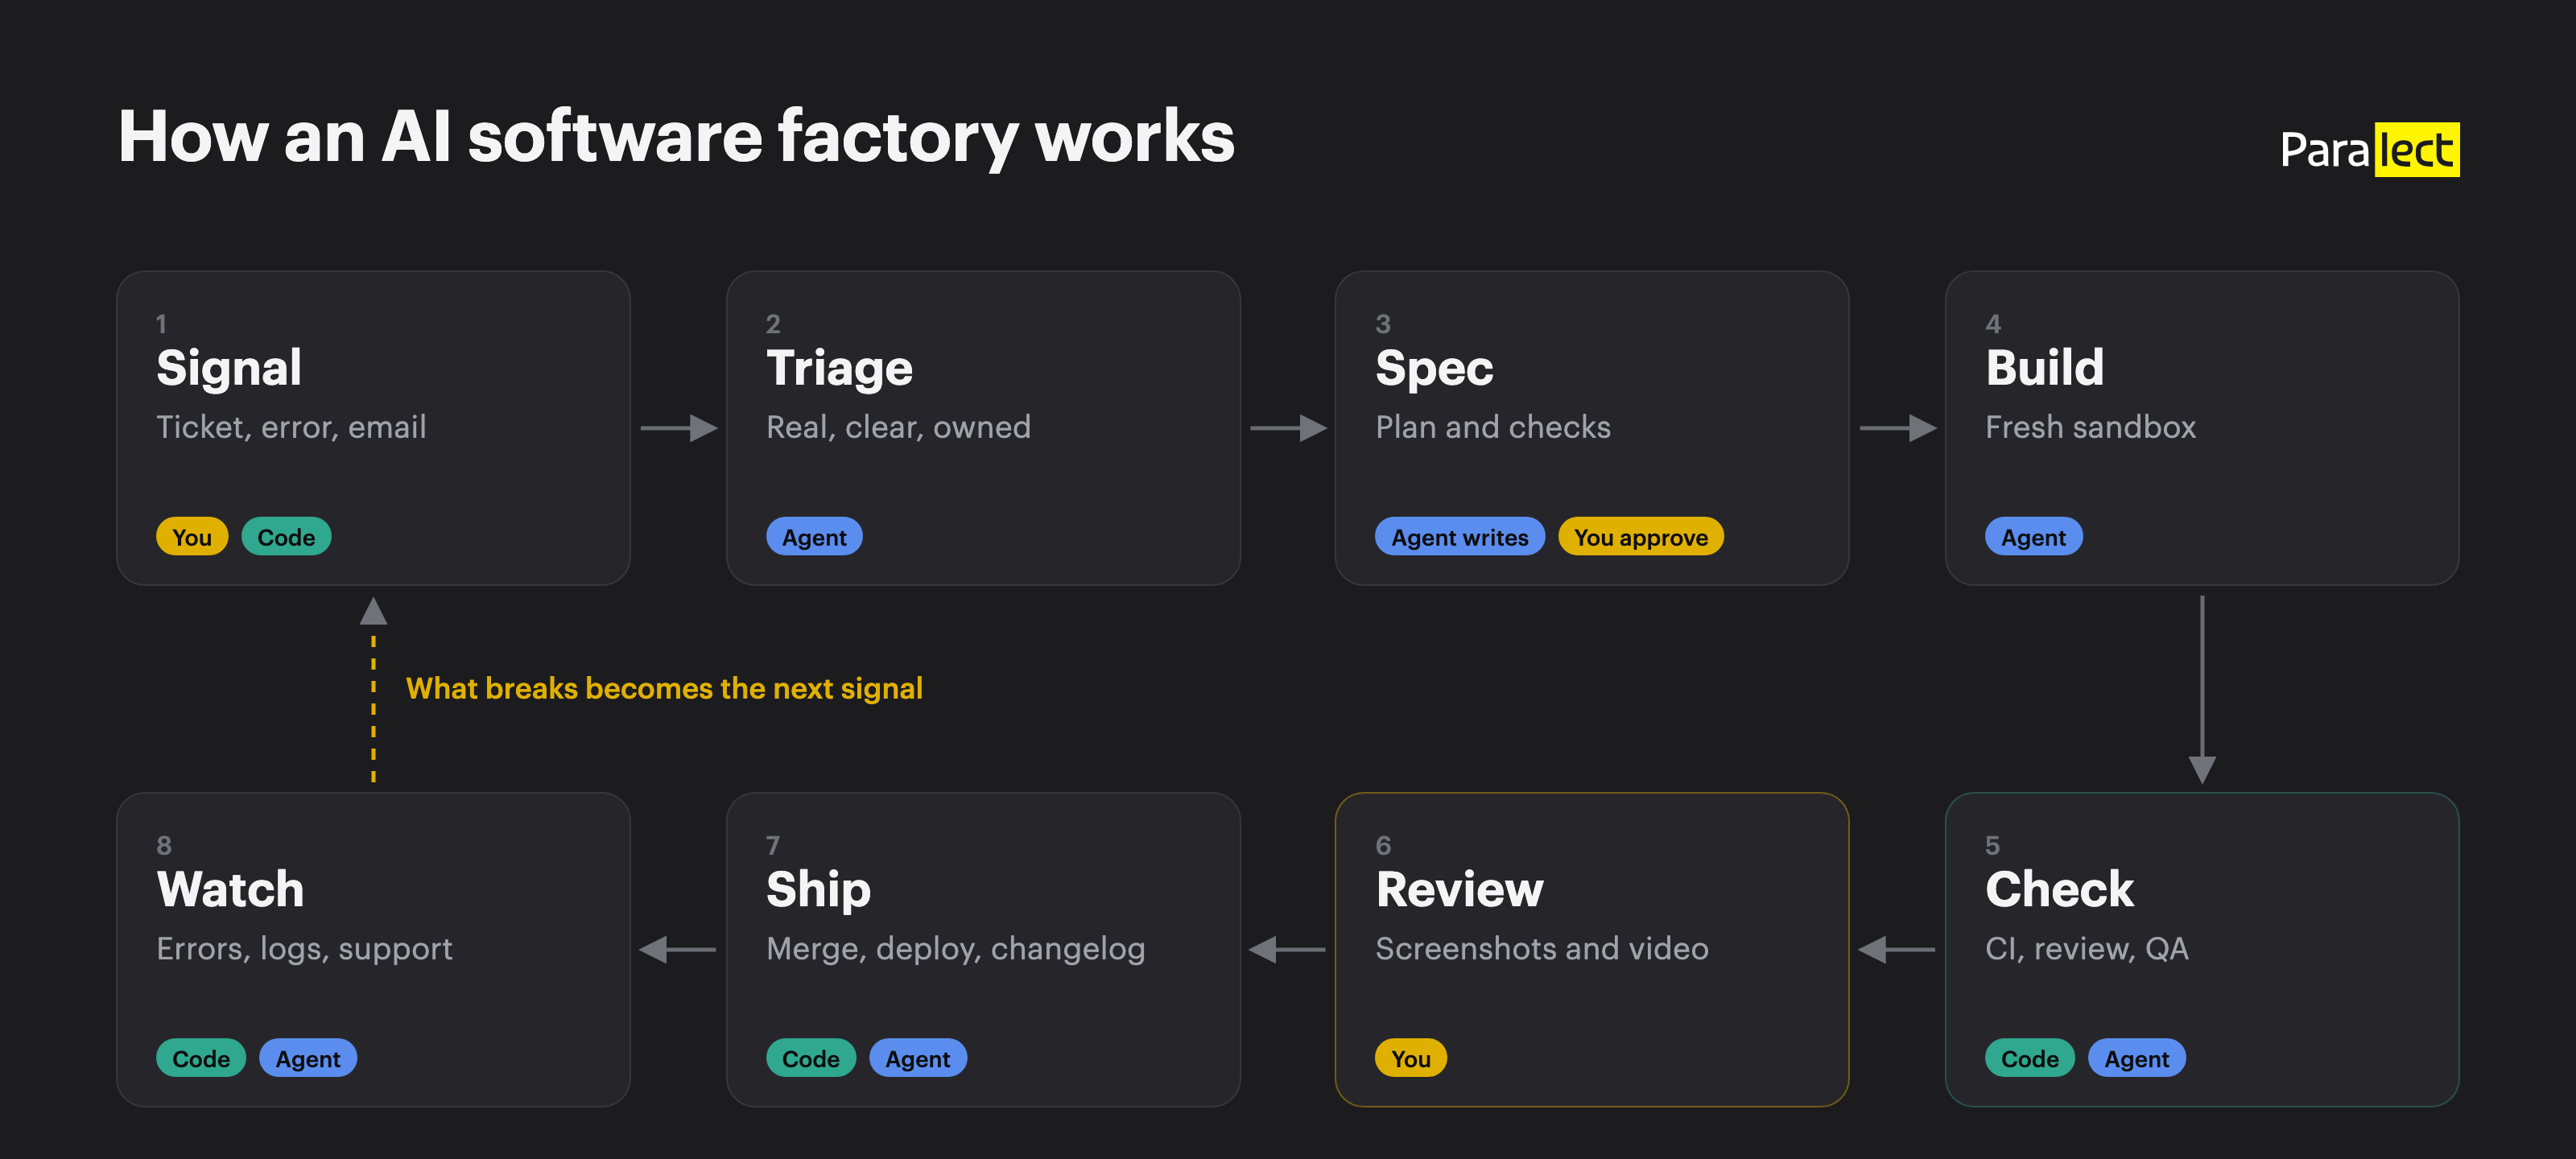
- 1Signal
Anything that says the software should change: a Linear ticket, a Sentry alert, a failing CI job, a customer email, your own idea. Most factories start with people filing tickets. The good ones also listen to production.
- 2Triage
An agent checks if the signal is real, if it's a duplicate, and if it's clear enough to build. Our rule: if a ticket doesn't have acceptance criteria that code can check, it goes back instead of getting built. This is the slowest part of the whole factory, because most backlogs are full of tickets like "improve onboarding" and nobody volunteers to rewrite them.
- 3Spec
Before writing code, the agent writes down what it will build and how to check it's done. A person approves it in the ticket. A misunderstanding caught here takes 2 minutes to fix. Caught in review, it takes a day.
- 4Build
The agent builds in a fresh sandbox with no production credentials, in a fresh session. Every step gets a new agent, so context doesn't rot and one confused session doesn't poison the next. Put a budget on it: 2 CI attempts per run is enough. If the second one is still red, the run stops and leaves a report in the ticket instead of trying forever.
- 5Check
The builder never grades its own work. CI decides if the work passes, not an agent saying "tests pass." Then a separate review agent reads the diff, and a QA agent clicks through the change on a preview deploy. Two rules worth stealing:
- Deleting or skipping a test sends the work back automatically.
- The agent can't edit its own rules, prompts or CI config in the same PR.
- 6Review
This is your job. You look at what changed, not how. More on this below.
- 7Ship
Merge, deploy, and let an agent write the changelog entry and update the help center.
- 8Watch
Errors, logs, support tickets and analytics flow back as new signals. When something breaks, trace it to the PR that caused it. Factory does this every night. It's also how you find out whether your checks work: if the review agent approved something that later broke, you know what to fix in the factory.
PostHog calls this self-driving: agents watch production, and when one finds a problem, another opens a PR. In October, 11% of their merged PRs started that way. A person still merges every one.
A 30-day plan
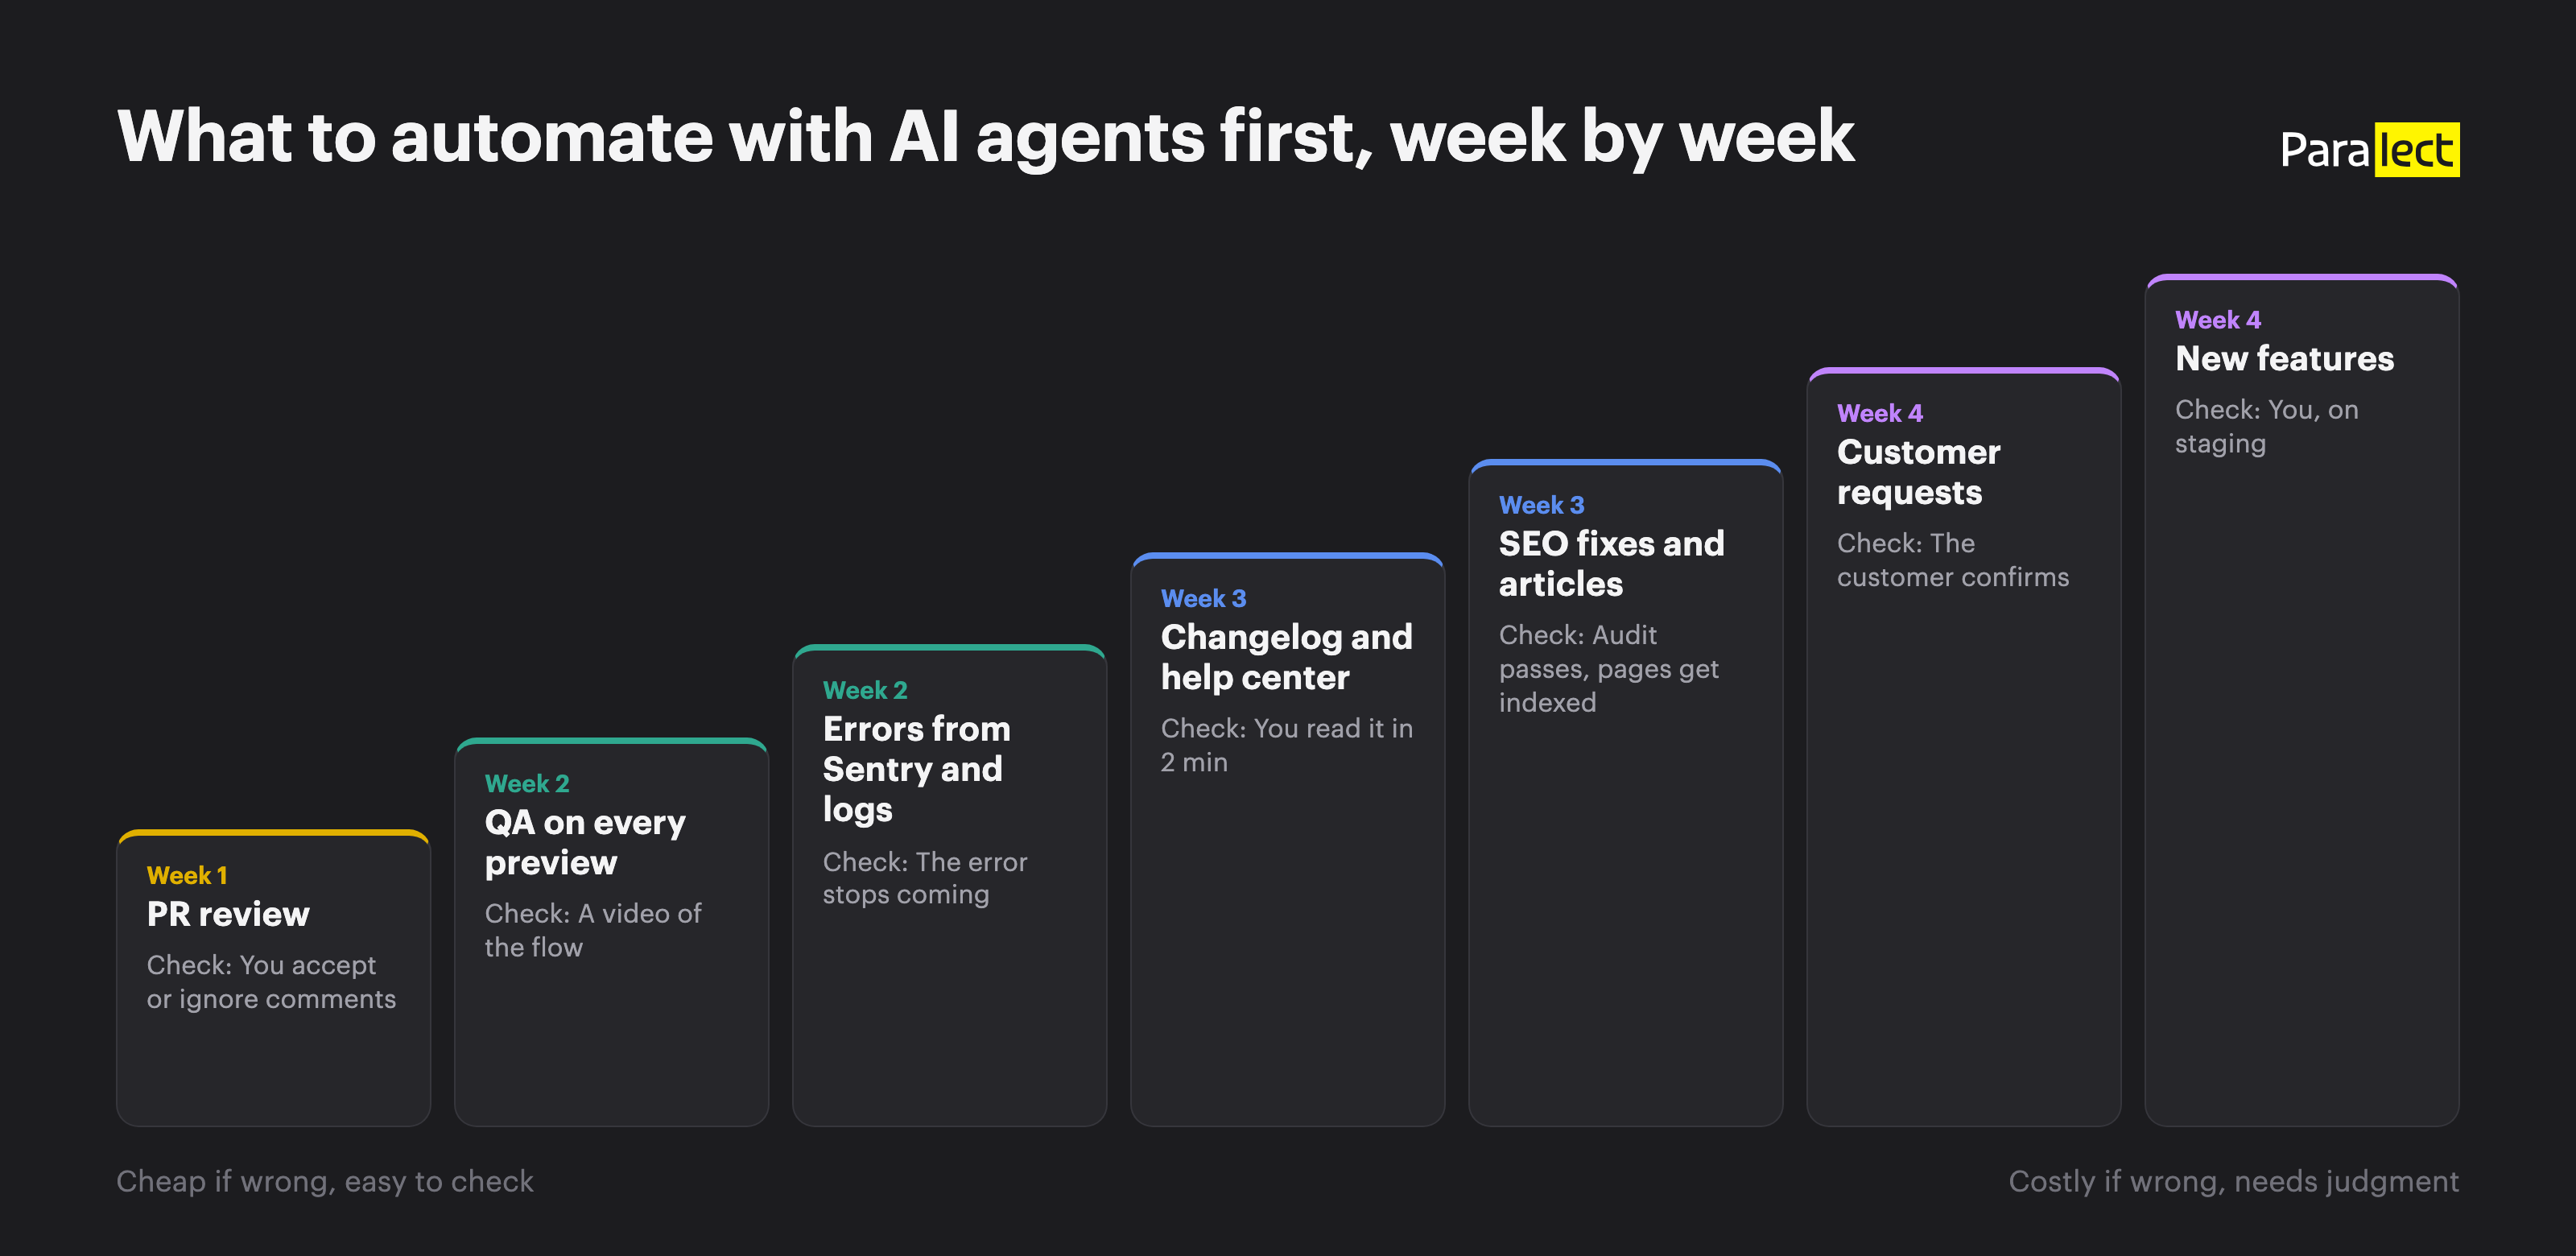
- 1Week 1: make the repo ready and turn on PR review
- Write
CLAUDE.mdorAGENTS.md: how to run the app, how to test it, the patterns to follow. - Get CI under 5 minutes. Add the lint rules for your top 5 conventions.
- Turn on preview deploys for every PR.
- Add the PR template from the "Standardize everything" section below.
- Put an AI reviewer on every PR. Tune its rules weekly from the comments you ignored.
If a new hire can't run your app and its tests on day 1, an agent can't either. Most teams find out their factory problem is a repo problem this week.
- Write
- 2Week 2: QA and errors
- Add a QA agent that clicks through the changed flow on every preview and records a video.
- Connect Sentry and your logs. Every new error becomes a ticket, and the agent opens a fix PR with a test that reproduces the bug.
- You still review every PR. That's fine for now: it shows you where the agents go wrong.
- 3Week 3: changelog, help center and SEO
- An agent drafts a changelog entry from every merged PR and updates the help articles the change touched. You approve it.
- Run an SEO audit every week. The agent fixes what it finds and drafts articles from real search data.
- 4Week 4: customer requests, new features, and the numbers
- Turn support emails and chats into tickets with steps to reproduce. Let the agent fix the small ones.
- Pick one label in Linear or GitHub, like
agent-ready. Tickets with that label and clear acceptance criteria go to the factory. - Look at the numbers below. Expand only the jobs where agent PRs merge without changes. Kill the ones that create more review work than they save.
We'll build the loop on your repo, your tracker and your monitoring, start with the safe jobs, and hand it over with the numbers that show what changed.
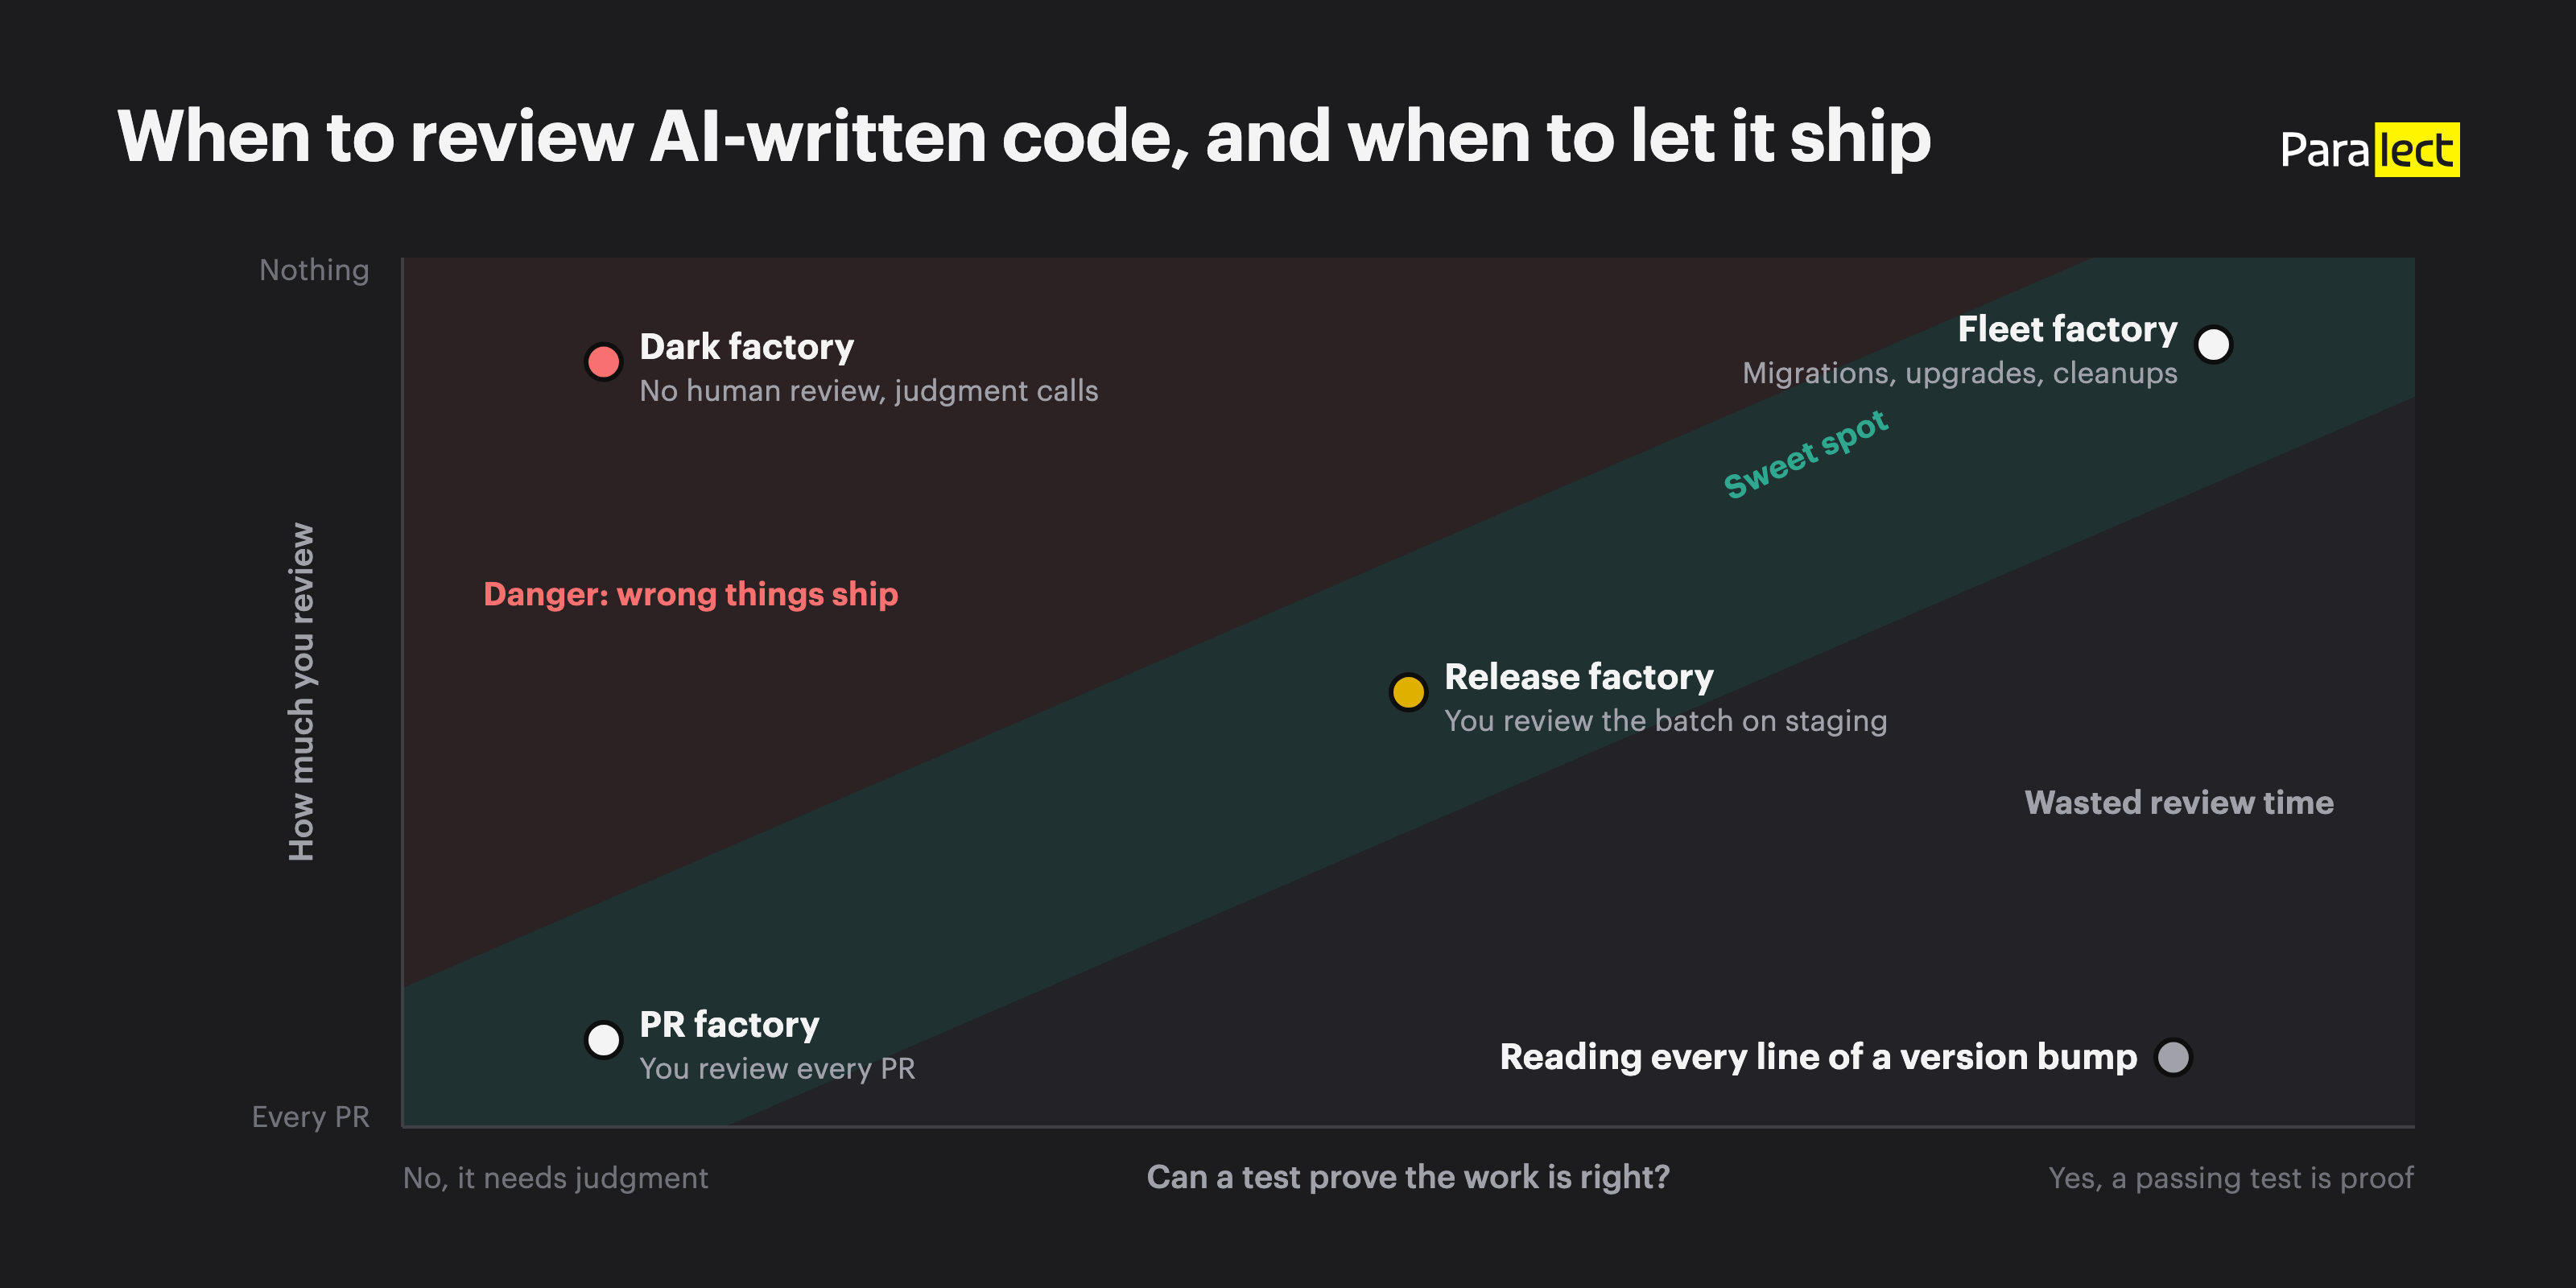
5 types of factory, and which one to build
| Type | How it works | Use it for |
|---|---|---|
| Dark factory | Takes a loose request, plans, builds, reviews and merges to production with no human | Prototypes and throwaway proofs of concept. Nothing with users. |
| Fleet factory | Same automation, but only for work with a clear, testable goal | Migrations, dependency upgrades, refactors, cleanups |
| PR factory | Agents build each ticket, you review every PR | Getting started, or code where mistakes are expensive |
| Release factory | You plan 10 to 20 tickets together, agents build them in parallel, you review the batch on staging | Most product work, once your checks are good |
| Self-improving factory | A release factory that also turns production errors and analytics into new tickets | When you trust the loop and want it to fix what users hit |
- Spotify's Honk has merged more than 2.5 million automated maintenance PRs, most of them automerged with no human in the loop.
- Bun ported 535,496 lines of Zig to Rust in 11 days, with up to 64 Claude instances at once and about $165,000 in API tokens. It worked because the test suite already defined "correct": 100% of tests pass.
Standardize everything
CLAUDE.md or AGENTS.md, and enforce it with lint rules, not prose. A lint rule the agent can't skip beats a paragraph it can ignore.Loading editor...
## What changed
One sentence a customer would understand.

## Why
Link to the ticket, the Sentry issue or the customer request.

## Changed surfaces
Write "None" under a heading when nothing changed there.

### Database
| Table | Change |
| --- | --- |
| `invoices` | new column `paid_at`, nullable |

### Migrations
| Migration | Does | Data | Risk |
| --- | --- | --- | --- |
| `20261117_add_paid_at` | adds `paid_at` | backfills from payments | low, runs in under a minute |

### Screens
| Screen | Change |
| --- | --- |
| `/app/invoices` | new "Paid on" column, filter by paid date |

### Customer communication
| Channel | Change |
| --- | --- |
| Email | "Invoice paid" email now shows the payment date |
| Web notification | none |

## Before / after
Screenshots of every changed screen, desktop and mobile.

## Video
30-60 seconds of the agent clicking through the flow on the preview.

## How it was checked
- [x] CI green on first or second run
- [x] Review agent: 0 blocking comments
- [x] QA agent: flow recorded, no console errors

## Risk
Low / medium / high, and what to look at if it's not low.
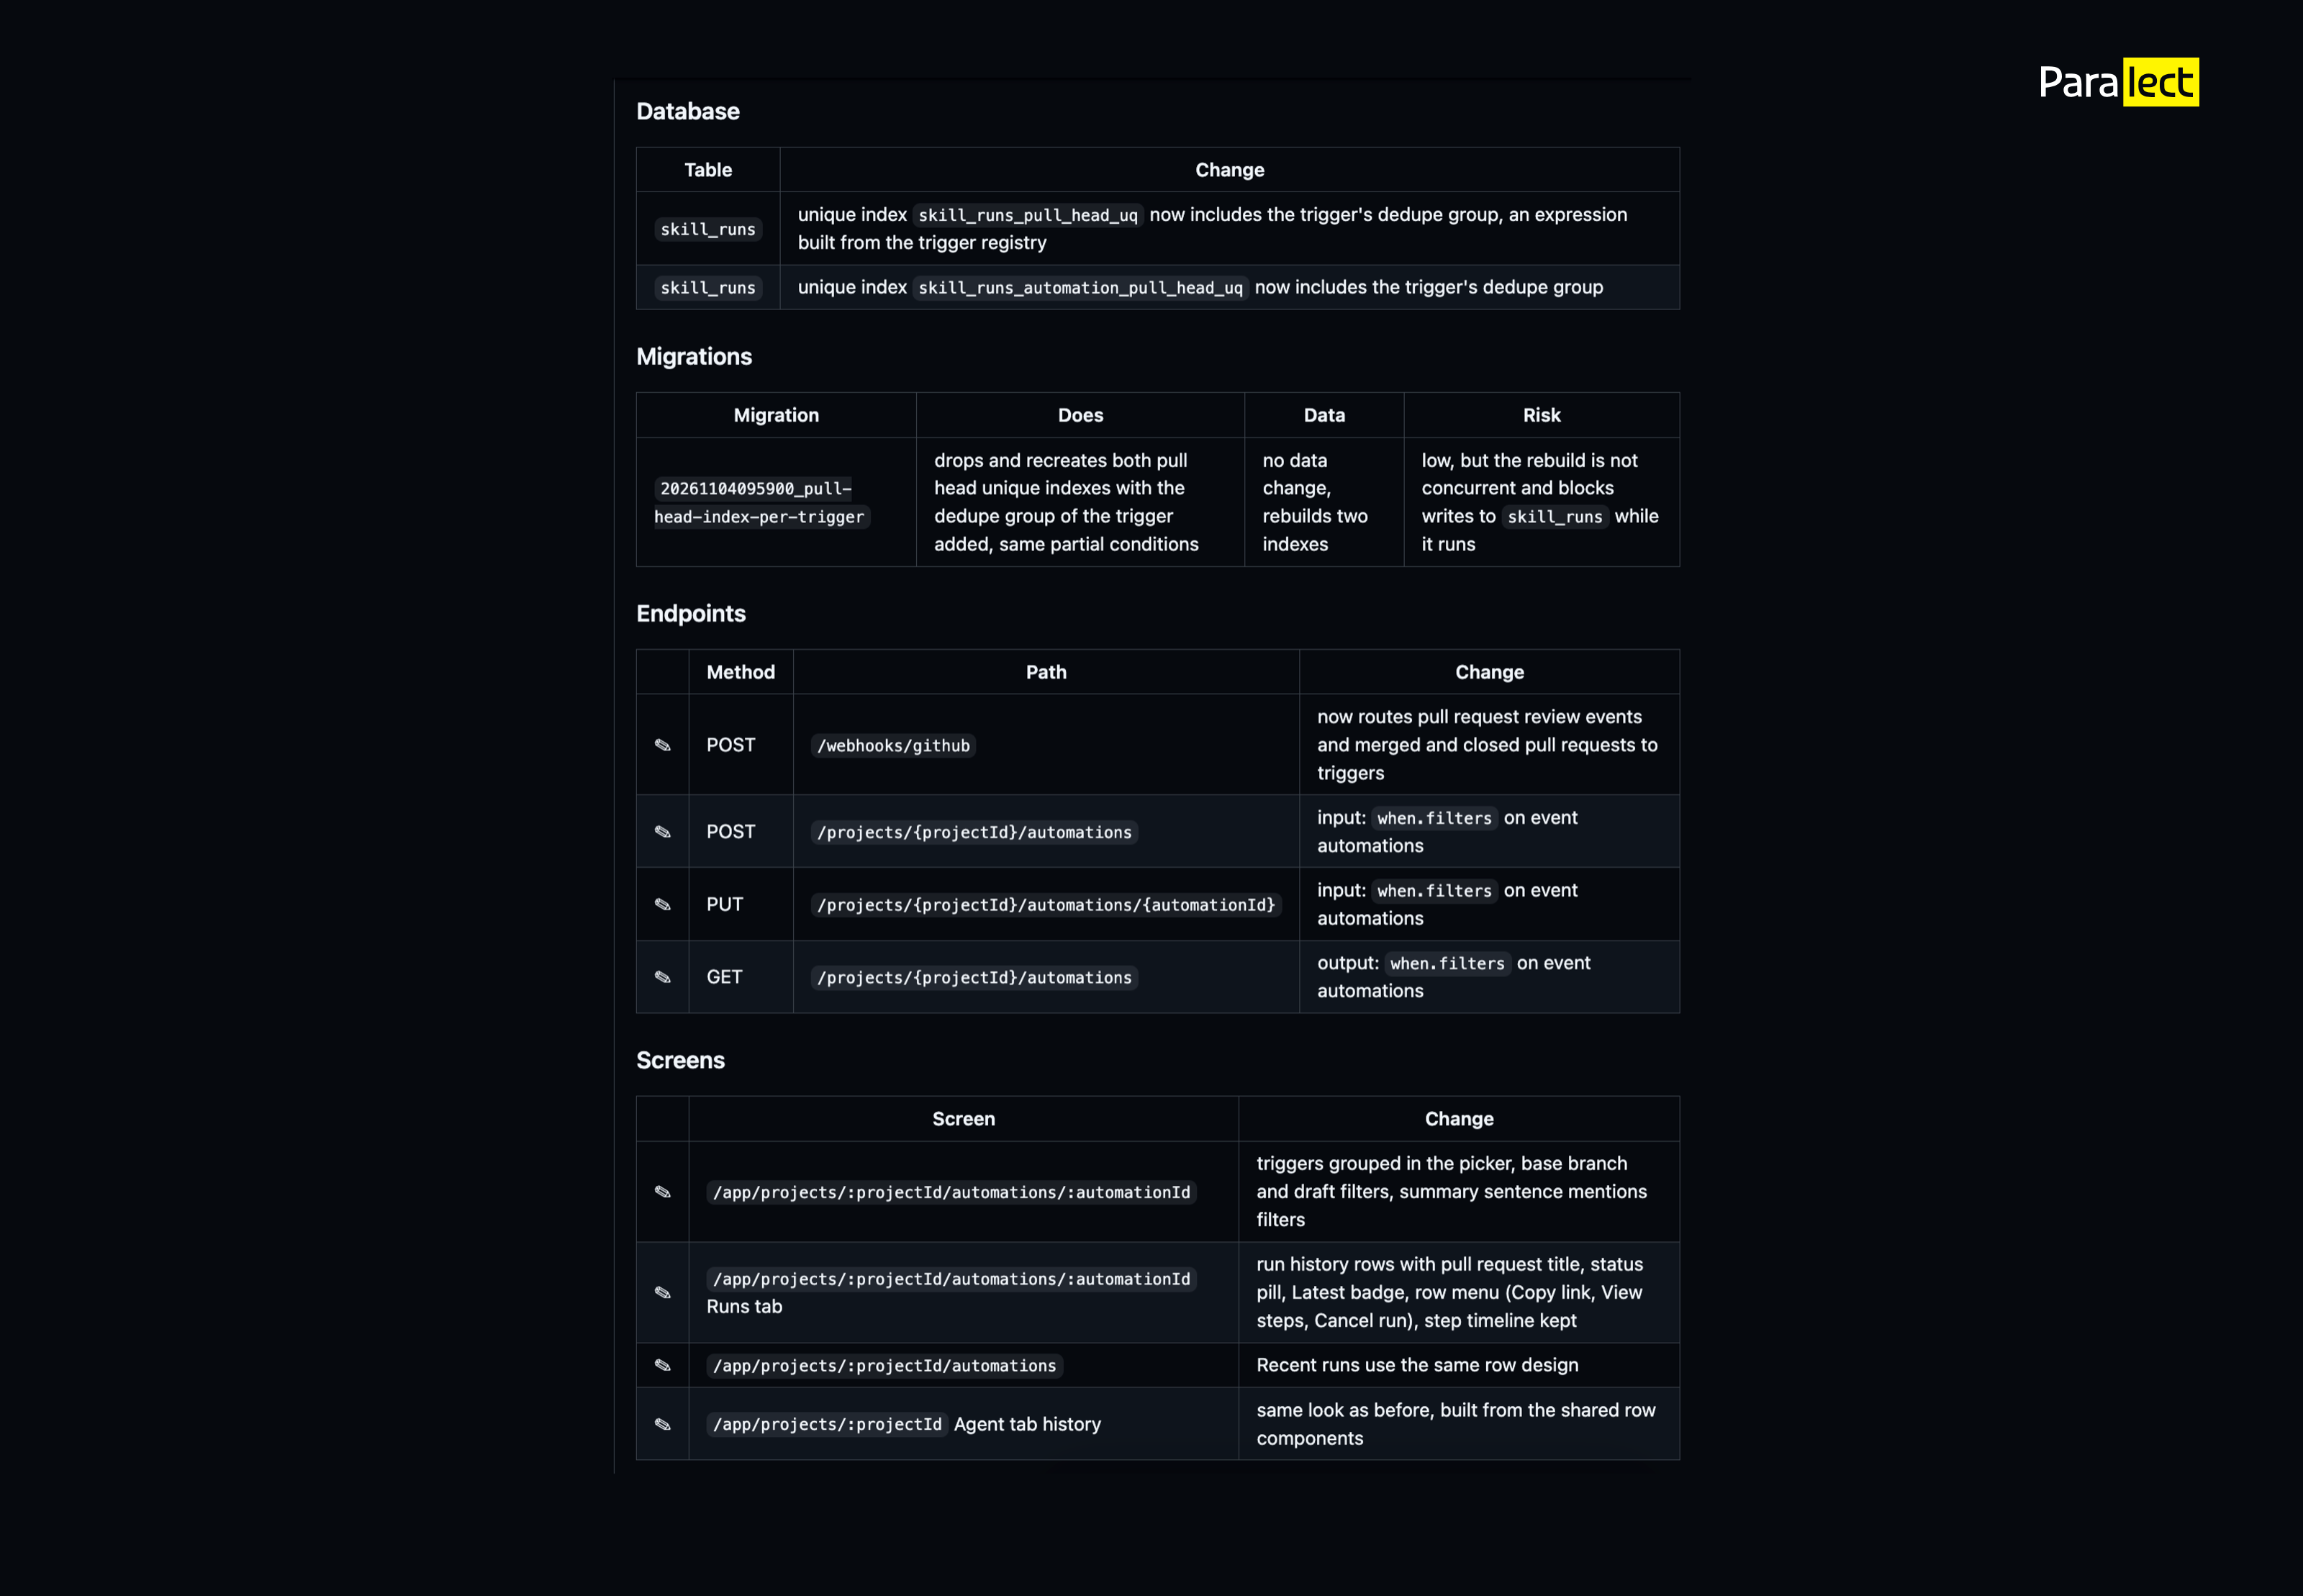
Agent instructions, lint rules, fast CI, preview deploys, a PR template with screenshots and video, and AI review on every PR. We do it with your developers, so they keep it running.
Review screenshots and videos, not diffs
- Screenshots of every changed screen, before and after. You catch a broken layout in 1 second.
- A short video of the flow on the preview deploy. You see the empty state, the loading state and the error message nobody thought about.
- A plain-language summary at the top of the PR, not 3 paragraphs of "I updated the component to use the new hook."
- The changed surfaces: database, migrations, screens and customer emails, so you see what a change touches before you open the diff.
- The risk score, so you know which 3 PRs out of 39 deserve a real read.
Local or remote
| | Local factory | Remote factory |
|---|---|---|
| Runs on | Your laptop, in an app | A server or the cloud |
| Runs when | Your laptop is open | Always, triggered by webhooks and schedules |
| Pays with | Your Claude or ChatGPT subscription | API usage, Team seats, or a subscription on a VPS |
| Good for | Solo founders and small teams, doing your own tickets faster | Teams, work that starts without a person (errors, PRs, releases) |
| Examples | Claude and Codex desktop apps, T3 Code, Conductor | Claude Code scheduled tasks and GitHub Actions, Capy, Factory, a VPS |
Tools to start with

The remote pieces




Measure it, or it's theater
| Metric | What it tells you |
|---|---|
| Regret-free merge rate | Share of agent PRs that merged and didn't need a revert or a follow-up fix. The main number: climb it until you can automerge. |
| Share of merged PRs by agents | Kaching is at 77%, PostHog at about 70%. |
| Merged PRs per day | Kaching went from 10 to 39. If this doesn't move, the factory isn't working. Count merges, not PRs opened. |
| Bugs traced to agent PRs | Compare with bugs from human PRs. When agents break things less often, give them more autonomy. |
| Cost per merged PR | Tokens and compute divided by what merged. Not per run, per merge. |
| Time from signal to merge | How long an error, a request or a ticket waits before it's fixed. |
What a factory won't do for you
- Decide what to build. Product discovery, talking to customers and choosing the next bet stay with people.
- Design your architecture. New systems, big refactors, performance work and new domains need someone who holds the whole picture in their head.
- Fix unclear tickets. A factory multiplies whatever goes into it. Vague tickets turn into wrong features, faster.
- Save a bad codebase. Agents copy what they see. Clean it up first, or the factory makes more of it.
- Run without an owner. Someone has to tune the review rules, fix the flaky tests and read the reports every week. That's the factory engineer's job, and it's a real job.
We set up the whole loop on your stack: agent-ready repo, CI gates, AI review, QA videos on previews, Sentry-to-PR fixes, changelogs, help center and SEO. Your team keeps it, and the numbers show what it changed.
Sources
- Eno Reyes on Factory's software factory, November 2026, and Factory 2.0: from coding agents to software factories, June 2026
- Spotify: coding is no longer the constraint, June 2026
- Bun: porting Bun to Rust, July 2026
- PostHog: can software factories actually work?, August 2026, and we made our CI self-driving, October 2026
- Warp: we are now factory engineers, not product engineers, June 2026, and Factory benchmarks, September 2026
- No AI Slop Manifesto, November 2026
- Mark Ajzenstadt: the 10 parts of a software factory, November 2026
- Lauren Tan: you don't need a software factory, November 2026
- Matt Pocock: in defense of the term and a brief history of AI coding, November 2026
- Claire Vo: what she sees in real engineering teams, November 2026
- Zach Lloyd: what a software factory is not, November 2026
- Thariq Shihipar: software factories are a temporary problem, November 2026
- Kaching: 77% of merged PRs from agents and what it costs, November 2026
- Top agentic IDEs, Paralect Stack
Ship faster than
your competition
Focus on customers and sales while we handle product delivery. Hire a dedicated AI maker or a whole product team.


